When two artificial-intelligence systems are asked to debate one another, their apparent opinions can change surprisingly quickly.
But that does not necessarily mean one AI has persuaded the other.
New research suggests that part of the movement may come from biases already built into the models themselves.
A study published in Nature Communications on 22 September 2026 examined how large language models change their stated positions during multi-step conversations.
The researchers tested several LLMs across 12 questions ranging from climate change and social issues to everyday preferences such as music.
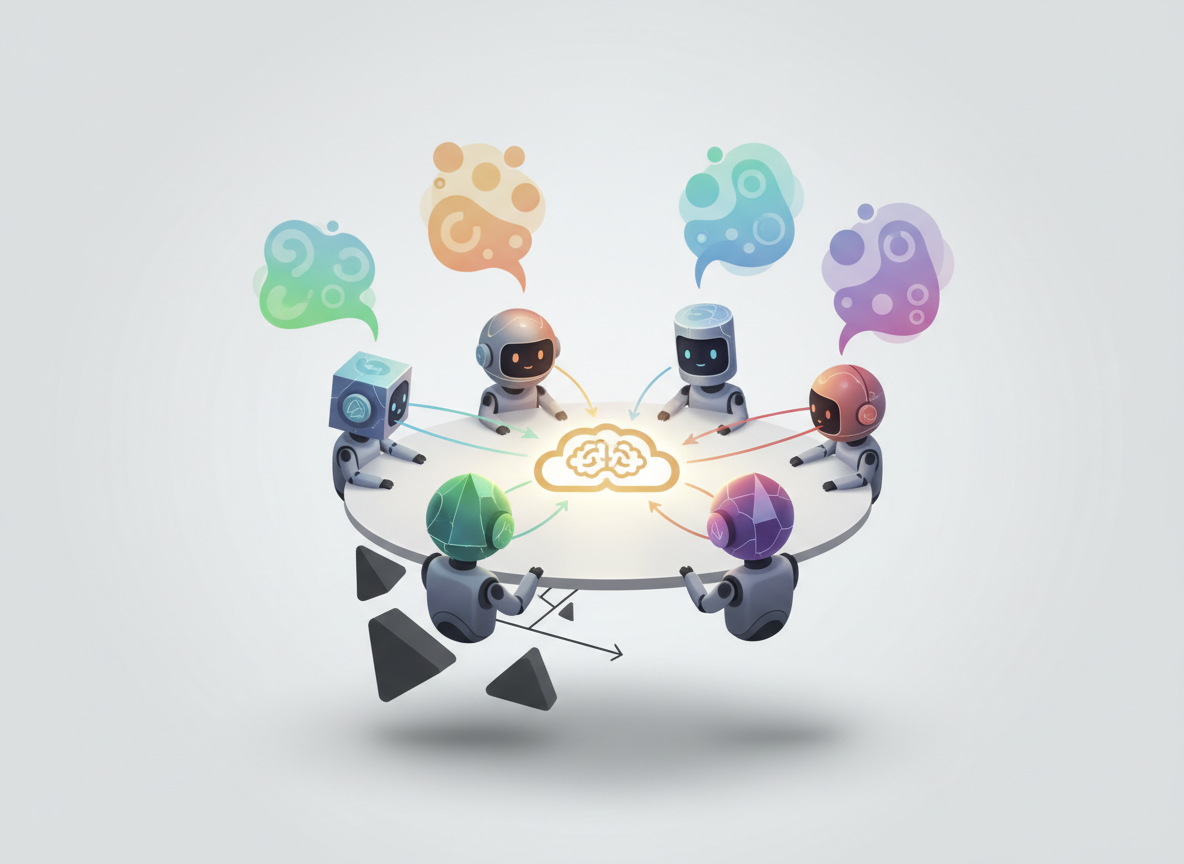
They found that the models’ opinions tended to converge rapidly toward a shared position, or what the authors describe as an “opinion attractor”.
Crucially, the destination was not determined only by the arguments exchanged during the conversation. It was also influenced by three systematic tendencies: a default topic bias, a tendency to agree with a prompted statement and an anchoring bias toward the position introduced at the start of the discussion.
When one model was fine-tuned on strongly opinionated material, including misinformation, the location of that shared opinion shifted accordingly.
Researchers are increasingly using AI agents to simulate people
Large language models are no longer used only to answer individual questions.
Researchers are also placing multiple AI agents into simulated environments and allowing them to interact with one another.
These systems can be used to explore how opinions spread, how groups form consensus or how different communication strategies might influence a population.
The attraction is obvious.
Running thousands of simulated AI conversations can be faster and cheaper than recruiting thousands of people for repeated experiments.
But this creates a fundamental methodological problem.
An LLM does not enter a conversation as a neutral participant. Its responses are shaped by training data, fine-tuning, alignment procedures, prompting and the way the question is phrased.
If these influences are mistaken for genuine social interaction, researchers may conclude that an AI simulation is showing human-like opinion dynamics when it is actually showing model-specific behaviour.
The study separated conversation effects from three types of bias
Vincent C. Brockers, David A. Ehrlich and Viola Priesemann developed a Bayesian framework designed to separate the effect of interaction from several recurring sources of bias.
The first was topic bias.
This describes the model’s tendency to lean toward a particular position on a topic before the conversation meaningfully develops.
The second was agreement bias.
This is the tendency to favour agreement with the statement presented in the prompt, regardless of the underlying issue.
The third was anchoring bias.
This occurs when the position introduced by the initiating agent disproportionately influences where the conversation moves.
The framework allowed the researchers to estimate how much opinion change could be attributed to interaction and how much appeared to come from these systematic tendencies.
The AI agents discussed 12 different questions
The researchers did not restrict the experiment to a single controversial issue.
The LLM agents engaged in repeated dialogues across 12 questions covering topics that included climate change, societal justice and personal preferences such as music.
This was important because a model may behave differently depending on the subject.
A system may have a strong pre-existing tendency on one topic and a much weaker tendency on another.
The researchers compared multiple models, including Mixtral-based systems and GPT-4o-mini, to determine whether the same opinion dynamics appeared consistently across model families.
They did not.
The relative importance of interaction, topic bias, agreement bias and anchoring differed markedly between the models.
The conversations moved quickly toward a shared position
Across the experiments, the models’ stated opinions tended to move rapidly toward a common position.
The researchers describe this position as an attractor because the conversation repeatedly pulled the agents toward it.
Once the agents moved closer to the attractor, subsequent turns produced progressively smaller changes.
Both the estimated effect of genuine interaction and the influence of the measured biases declined as the conversation continued.
In other words, most of the movement happened relatively early.
That pattern is important for anyone using LLM agents to model debate or deliberation because a rapid artificial consensus may not represent the way human disagreement persists over time.
Agreement can look like persuasion when it is actually a model tendency
One of the clearest methodological risks is agreement bias.
Suppose one AI agent presents a statement and another agent shifts toward agreeing with it.
It would be tempting to interpret that movement as evidence that the second agent found the argument persuasive.
But if the model has a general tendency to agree with statements placed in front of it, part of the shift may have little to do with the quality of the argument.
The new framework attempts to estimate this difference.
That distinction becomes especially important when researchers use LLMs as stand-ins for people in social-science experiments.
A model that agrees because of prompt structure is not necessarily reproducing a human process of persuasion.
The first opinion introduced can also pull the conversation
Anchoring created another source of apparent opinion change.
The initiating position could influence the trajectory of the discussion even after multiple conversational turns.
This means that two otherwise similar simulations could produce different outcomes simply because the conversation started from different positions.
For social simulation, that creates a practical problem.
If a study runs an AI debate once and reports the final consensus, the result may partly reflect an arbitrary starting condition rather than a stable underlying social process.
Repeated simulations with different initial positions may therefore be necessary to understand how robust an apparent consensus actually is.
Different models showed different bias profiles
The study also found that there is no single “LLM opinion dynamic”.
The models differed substantially in how strongly they responded to interaction and in which biases dominated their behaviour.
This matters because researchers sometimes speak about large language models as if they were interchangeable.
But a simulation conducted with one model may produce different group dynamics from the same simulation conducted with another.
Model updates could also change the result over time.
A study based on one version of a commercial model may therefore be difficult to reproduce if the provider later changes the system’s training, alignment or response behaviour.
Fine-tuning shifted where the models eventually converged
One of the study’s strongest demonstrations came from deliberately changing a model’s training.
The researchers fine-tuned an LLM on different sets of strongly opinionated statements.
Some of the training material included misinformation.
After fine-tuning, the location of the model’s opinion attractor shifted in the direction of the material it had been trained on.
This shows that the eventual consensus reached by interacting AI agents can depend on information embedded before the conversation begins.
The agents may appear to be negotiating toward a common position, while the destination is partly predetermined by the statistical tendencies created during training.
This is not evidence that AI conversations work the same way as human conversations
The study is specifically about interactions between large language models.
It does not show that humans converge toward opinions in the same way.
Human beliefs are shaped by identity, memory, emotion, social relationships, incentives, lived experience and long-term commitments.
LLMs generate responses from learned statistical patterns and the context supplied to them.
That difference is precisely why the researchers developed a method for quantifying model-specific biases.
Before an LLM can be used as a proxy for human behaviour, researchers need evidence that the simulated dynamics resemble the human process they are intended to represent.
The study also does not show that chatbots are changing users’ political opinions
The findings could easily be interpreted too broadly.
The experiments examined AI agents interacting with other AI agents.
They did not measure whether human users became more likely to accept a political, social or commercial position after talking to a chatbot.
The study therefore cannot establish that everyday AI assistants are manipulating human opinions.
Its relevance is methodological: if researchers or organisations use interacting AI agents to forecast how people might debate, polarise or reach consensus, they need to distinguish simulated social influence from the model’s own built-in tendencies.
The findings matter for synthetic market research as well
The same concern extends beyond academic social simulation.
Companies are increasingly experimenting with synthetic respondents and AI-generated personas to test advertising, products, messages and customer reactions.
If these simulated consumers are asked to discuss a product or react to one another, rapid convergence could be mistaken for genuine market consensus.
Agreement bias could make a concept appear more acceptable than it would be among real consumers.
Topic bias could reflect patterns in the model’s training data rather than the attitudes of a target population.
Anchoring could make early information disproportionately shape the final result.
The study therefore reinforces a basic research principle: synthetic participants should be validated against the human population they are supposed to represent.
There are important limitations to the experiment
The researchers tested a limited set of models and a limited set of questions.
Newer or differently aligned systems may show different patterns.
The measured opinion dynamics also depend on how an “opinion” is elicited from a language model.
Unlike a person, an LLM does not necessarily possess a stable internal belief that can be measured directly.
Its expressed position can change with prompt wording, conversational context and sampling settings.
The Bayesian framework provides a way to separate several identifiable influences, but it cannot guarantee that every possible source of model behaviour has been captured.
The results should therefore be understood as a method for analysing observable opinion-like behaviour in LLMs rather than evidence that the systems hold beliefs in the human sense.
More realistic AI agents are not automatically better social models
As language models become more fluent, their conversations increasingly resemble human dialogue.
That realism can make simulations feel convincing.
But surface realism and behavioural validity are different things.
An AI agent can produce persuasive arguments, express uncertainty and revise its position while still following dynamics that are unlike those of human participants.
The new study provides a concrete example.
What looks like persuasion may partly be agreement bias. What looks like consensus may partly be anchoring. What looks like a shared conclusion may be an attractor inherited from training.
The bigger lesson is to audit the model before trusting the simulation
LLM-based social simulations could still be useful.
They make it possible to run complex conversational experiments at a scale that would be difficult with human participants.
But the new research suggests that the model itself needs to become part of the measurement process.
Researchers need to know how strongly a system tends to agree, how much it anchors on the first position it sees and whether it begins a topic with a strong default stance.
Without that information, an AI society may tell researchers as much about the model that generated it as about the society they hoped to simulate.
Source Information
Study Title: Disentangling interaction and bias effects in opinion dynamics of large language models
Authors: Vincent C. Brockers, David A. Ehrlich and Viola Priesemann
Journal: Nature Communications
Published: 22 September 2026
Dataset: Multiple large language models engaged in multi-step dialogues across 12 questions spanning social, scientific and everyday topics.
Method: The researchers used a Bayesian framework to separate interaction-driven opinion change from topic bias, agreement bias and anchoring bias, and then tested how fine-tuning on strongly opinionated material affected the models’ eventual opinion attractors.
Main finding: LLM opinion trajectories rapidly converged toward shared attractors. Both conversational influence and measured biases declined over time, bias profiles differed across models, and fine-tuning on strongly opinionated statements, including misinformation, shifted the position toward which models converged.
DOI: 10.1038/s41467-026-77340-3