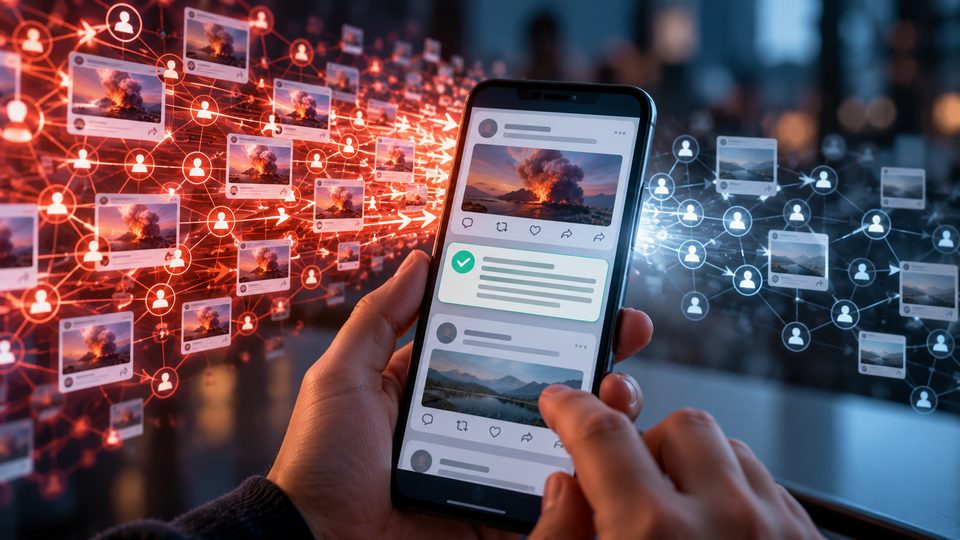

Fake news is increasingly difficult to detect when the deception is spread across both words and images. A photograph can appear authentic while its caption changes the context, or a plausible block of text can be paired with an unrelated image to create a misleading story. That combination is a growing challenge for automated moderation systems, which must judge not only whether each individual element looks credible, but also whether the elements make sense together.
Research published in Scientific Reports on 2 October 2026 presents a new approach designed specifically for that problem. The model, called MLCL, combines large vision-language modelling with multi-level contrastive learning to examine text, images and the relationship between them. Across two established real-world fake-news datasets, the researchers report that the system improved overall classification accuracy by 2.2 percentage points on Weibo and 1.5 percentage points on GossipCop compared with the strongest competing methods included in their experiments.
Why multimodal misinformation is difficult to detect
Traditional fake-news detection often begins with language. Models can learn patterns in wording, sentiment, structure or semantic content that distinguish misleading posts from legitimate ones. Image-based systems can separately examine visual content. Social-media misinformation, however, frequently exploits the gap between these channels. The text may be ordinary and the image may be genuine, while the combination creates a false implication.
This means a useful detector needs to do more than extract strong text and image features independently. It must also learn when those features reinforce one another, when they contradict one another and which source of information deserves greater weight for a particular post.
Jun Li, Linghao Yan, Qingxue Liu, Suli Zhang and colleagues built MLCL around that problem. Rather than relying on a single representation for each modality, the architecture deliberately extracts information at several levels and then aligns those representations before making its final classification.
How the model works
For written content, the system uses BERT and CLIP encoders to capture textual information at different granularities. For visual content, ResNet and CLIP are used to produce complementary image representations. A large vision-language model adds another layer by turning visual information into text-based representations that can reflect both local image details and broader context.
The researchers then apply contrastive learning, a technique that trains a model to pull related representations closer together while pushing dissimilar representations further apart. Within the text and image streams, a normalised InfoNCE loss is used to align features from the different encoders and reduce redundant information.
Before the modalities are fused, the model performs another alignment step across three modality-level representations. This combines InfoNCE with a batch-hard triplet loss. In practical terms, the model is trained not only to recognise consistency between matching information, but also to learn relative distances between examples that should and should not resemble one another.
A modality-wise attention module then determines how strongly the different streams should contribute to the final representation. This matters because not every fake-news post is deceptive in the same way. In one case, the wording may contain the strongest clue. In another, the mismatch between an image and its surrounding context may be more informative.
Testing the system on Weibo and GossipCop
The team evaluated MLCL on two real-world benchmark datasets, Weibo and GossipCop. These provide a useful test because they represent different social-media and news environments rather than a single narrowly constructed laboratory dataset.
Across the reported experiments, MLCL outperformed the comparison methods. Overall accuracy improved by 2.2 percentage points on Weibo and by 1.5 percentage points on GossipCop. In a mature machine-learning task where leading models are often separated by relatively small margins, those gains suggest that the additional cross-modal alignment was contributing useful information rather than simply adding architectural complexity.
The result is particularly important because the proposed system does not treat a large vision-language model as a complete replacement for established encoders. Instead, it uses the large model as another source of contextual representation alongside BERT, CLIP and ResNet. The architecture therefore combines specialised feature extraction with a broader multimodal interpretation layer.
What the findings mean
The study points to a wider shift in misinformation research. Detecting manipulated or misleading content is becoming less about identifying one suspicious signal and more about testing whether multiple signals agree. As generative AI makes convincing text and imagery easier to produce, systems that examine relationships between modalities may become increasingly important.
For social platforms, news organisations and fact-checking systems, a model of this kind could eventually form part of a screening pipeline that prioritises suspicious posts for closer review. The study does not establish that MLCL is ready for autonomous real-world moderation, and an accuracy improvement on benchmark datasets should not be interpreted as proof that the model will generalise perfectly to rapidly changing misinformation campaigns.
False positives also carry meaningful consequences. A system that incorrectly labels legitimate journalism, satire or political speech as misinformation can create its own trust and governance problems. Automated detection is therefore most defensible when it supports human verification rather than replacing it, particularly where decisions affect visibility, reputation or public debate.
Important limitations remain
The evidence comes from two benchmark datasets, which is stronger than evaluation on a single dataset but still represents only part of the modern information environment. Language, platform culture, breaking-news events and manipulation techniques can change quickly. Performance on Weibo and GossipCop does not automatically establish equivalent performance across South African social media, multilingual content, private messaging platforms or future AI-generated campaigns.
The reported gains are comparative improvements under the researchers’ experimental conditions. They should therefore be understood as evidence that this architecture performed better than the tested alternatives, not as a universal measure of how much misinformation could be removed from a live platform.
Computational cost is another consideration. MLCL draws on multiple encoders and a large vision-language model, making it more complex than a lightweight classifier. Real-world deployment would have to balance accuracy against processing speed, infrastructure costs, privacy requirements and the volume of content being assessed.
Even with those constraints, the study demonstrates a useful principle: when misinformation is multimodal, the relationships between text and imagery can be as important as the content of either one in isolation. Better detection may therefore depend less on finding a single all-purpose AI model and more on teaching systems to compare several perspectives on the same post.
Source Information
Study Title: MLCL: LVLM-guided multi-level contrastive learning for fake news detection
Authors: Jun Li, Linghao Yan, Qingxue Liu, Suli Zhang et al.
Journal: Scientific Reports
Year: 2026
DOI: 10.1038/s41598-026-73360-7